
Infortrend AI Workload Storage
Overview
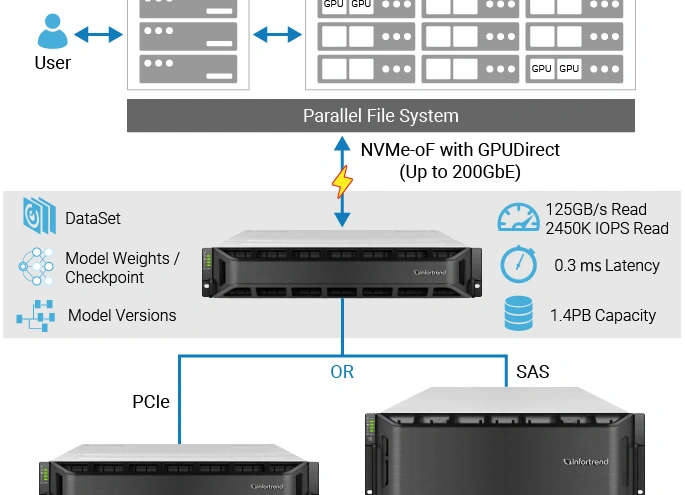
AI training, inference, and fine-tuning only create business value when GPUs stay busy — and storage is often the bottleneck. Purpose-built EonStor GS 5000U delivers up to 125GB/s read throughput, 2.4M IOPS, and 0.3ms latency over 200GbE with NVMe-oF and GPUDirect Storage, backed by an HA architecture with zero data loss and second-level recovery. Offered through our authorized Infortrend channel.
For base model training and large-scale inference, EonStor GS 5000U delivers up to 125GB/s read throughput and 2.4M IOPS at 0.3ms latency over 200GbE with NVMe-oF, eliminating GPU starvation across multi-node clusters.
GPUDirect Storage (GDS) moves data directly to GPU memory and bypasses the CPU, cutting latency and maximizing GPU utilization for training, inference, and metadata-intensive workloads.
For fine-tuning checkpoints and inference archiving, the system sustains 40GB/s writes, scales hot data with up to three NVMe SSD JBOFs, archives cold data on high-density JBODs, and auto-tiers across up to four media layers.
The POSIX-compatible GS File System integrates with parallel file systems such as Lustre, so compute servers access datasets and checkpoints without bottlenecks.
Fully redundant controllers, fans, and power supplies combined with HA architecture provide zero data loss (RPO=0), near-zero downtime, and recovery within seconds.
For cross-site disaster recovery, synchronous and asynchronous remote replication with EonCloud Gateway delivers sub-second RTO after a disaster.
Discuss this solution
Share your project scope and we will come back with an equipment list and indicative pricing.